DataWeave
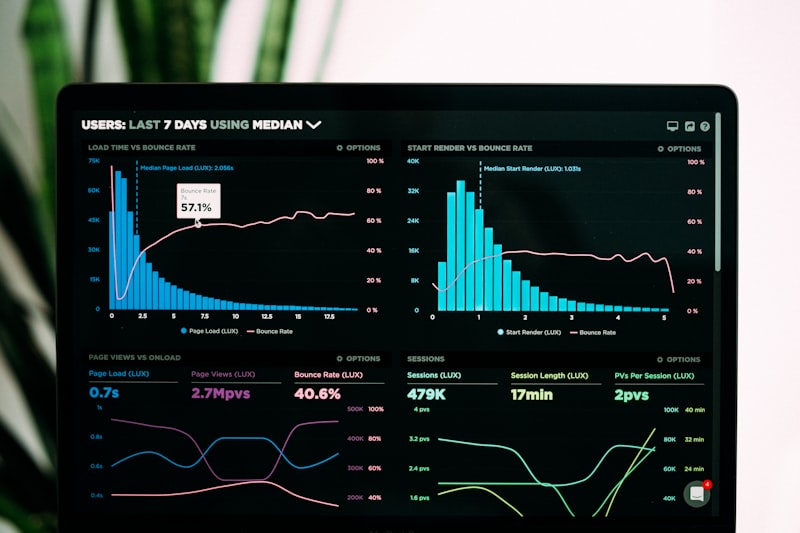
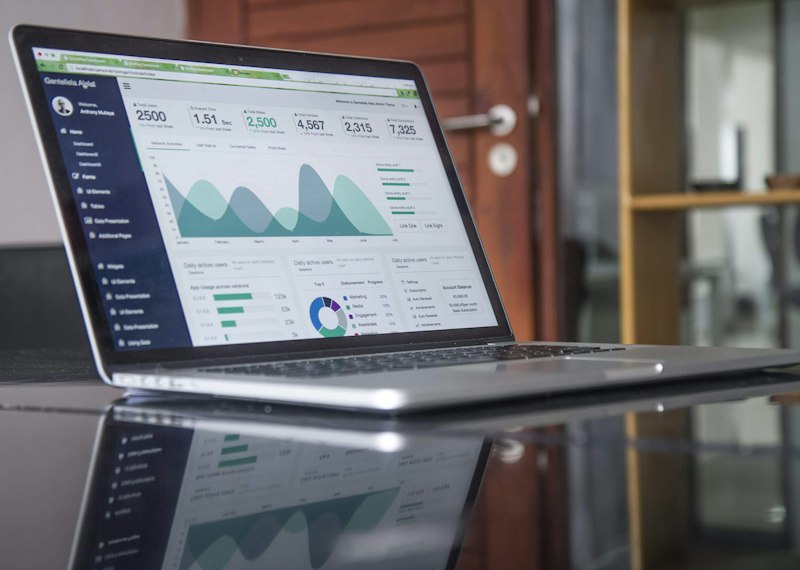
DataWeave lets non-technical analysts build and schedule data pipelines without writing code. It connects to REST APIs, SQL databases, Google Sheets, and cloud data warehouses, providing a live preview of transformations before execution.
// key outcome
Enabled analysts to own their own data pipelines, reducing data team tickets by 60%.
The Problem & User Context
Data analysts needed custom ETL pipelines but had to file tickets with the data engineering team for every new source or transformation, creating a 2-week backlog that blocked business decisions.
Approach & Tradeoffs
A React Flow-based canvas lets analysts connect nodes representing sources, transforms, and destinations. A Python/FastAPI backend validates and executes pipelines via Airflow. Real-time cell previews at each node eliminate guesswork.
Technical Architecture
React + React Flow for the canvas. FastAPI + Pydantic for the execution API. Apache Airflow for scheduling. Snowflake as the primary data warehouse target. Kubernetes for horizontal scaling of worker pods.
// tech stack
// architecture diagram
Add your architecture diagram here (Excalidraw, Figma, or SVG)
Screenshots & UI States
Results & Lessons Learned
- 60% reduction in data engineering support tickets
- Average pipeline creation time: 15 minutes (vs. 2-week queue)
- 40+ connectors including Salesforce, HubSpot, Stripe, and BigQuery
- Processing 500M+ rows per day in production
Explore the Code
All source code is open-source on GitHub. Issues, PRs, and feedback are always welcome.